

-
Near-eye displays for augmented and virtual reality (AR/VR) must simultaneously deliver a high spatial resolution, large depth of field (DOF), and efficient data handling1–4. These performance metrics conflict with an each other: improving the spatial resolution requires finer spatial light modulator (SLM) pixels, thereby proportionally increasing the volume of phase data to be computed and transmitted; extending the DOF demands wider angular coverage, while the finite aperture of the SLM cannot be provided without sacrificing the space-bandwidth product (SBP); and compressing the hologram data deteriorates the high-frequency spatial information essential for ensuring image quality. Neural approaches to expand the SBP, such as the neural étendue expander5, have successfully addressed individual facets of the problem; however, they have not resolved all three constraints simultaneously. The existing strategies address some of these challenges. Conventional CGH pipelines (Fig. 1a) drive a full-resolution SLM directly from the input scene, thus rendering the SBP intrinsically pixel-limited and fixing the focal plane. The neural étendue expander5 widens the field of view through a learned diffractive surface, thereby expanding the SBP to approximately 6×, but operates on a single focal plane and requires active hardware at the output. The prior diffractive super-resolution (SR) decoder6 is fully passive and achieves approximately 4× SBP improvement; however, it remains confined to a single projection plane and operates without the digital encoder needed to compress input data. As shown in the performance comparison with the representative approaches in Fig. 1c, no prior approach has simultaneously achieved high SBP gains, extended DOFs, data compression, and passive outputs.
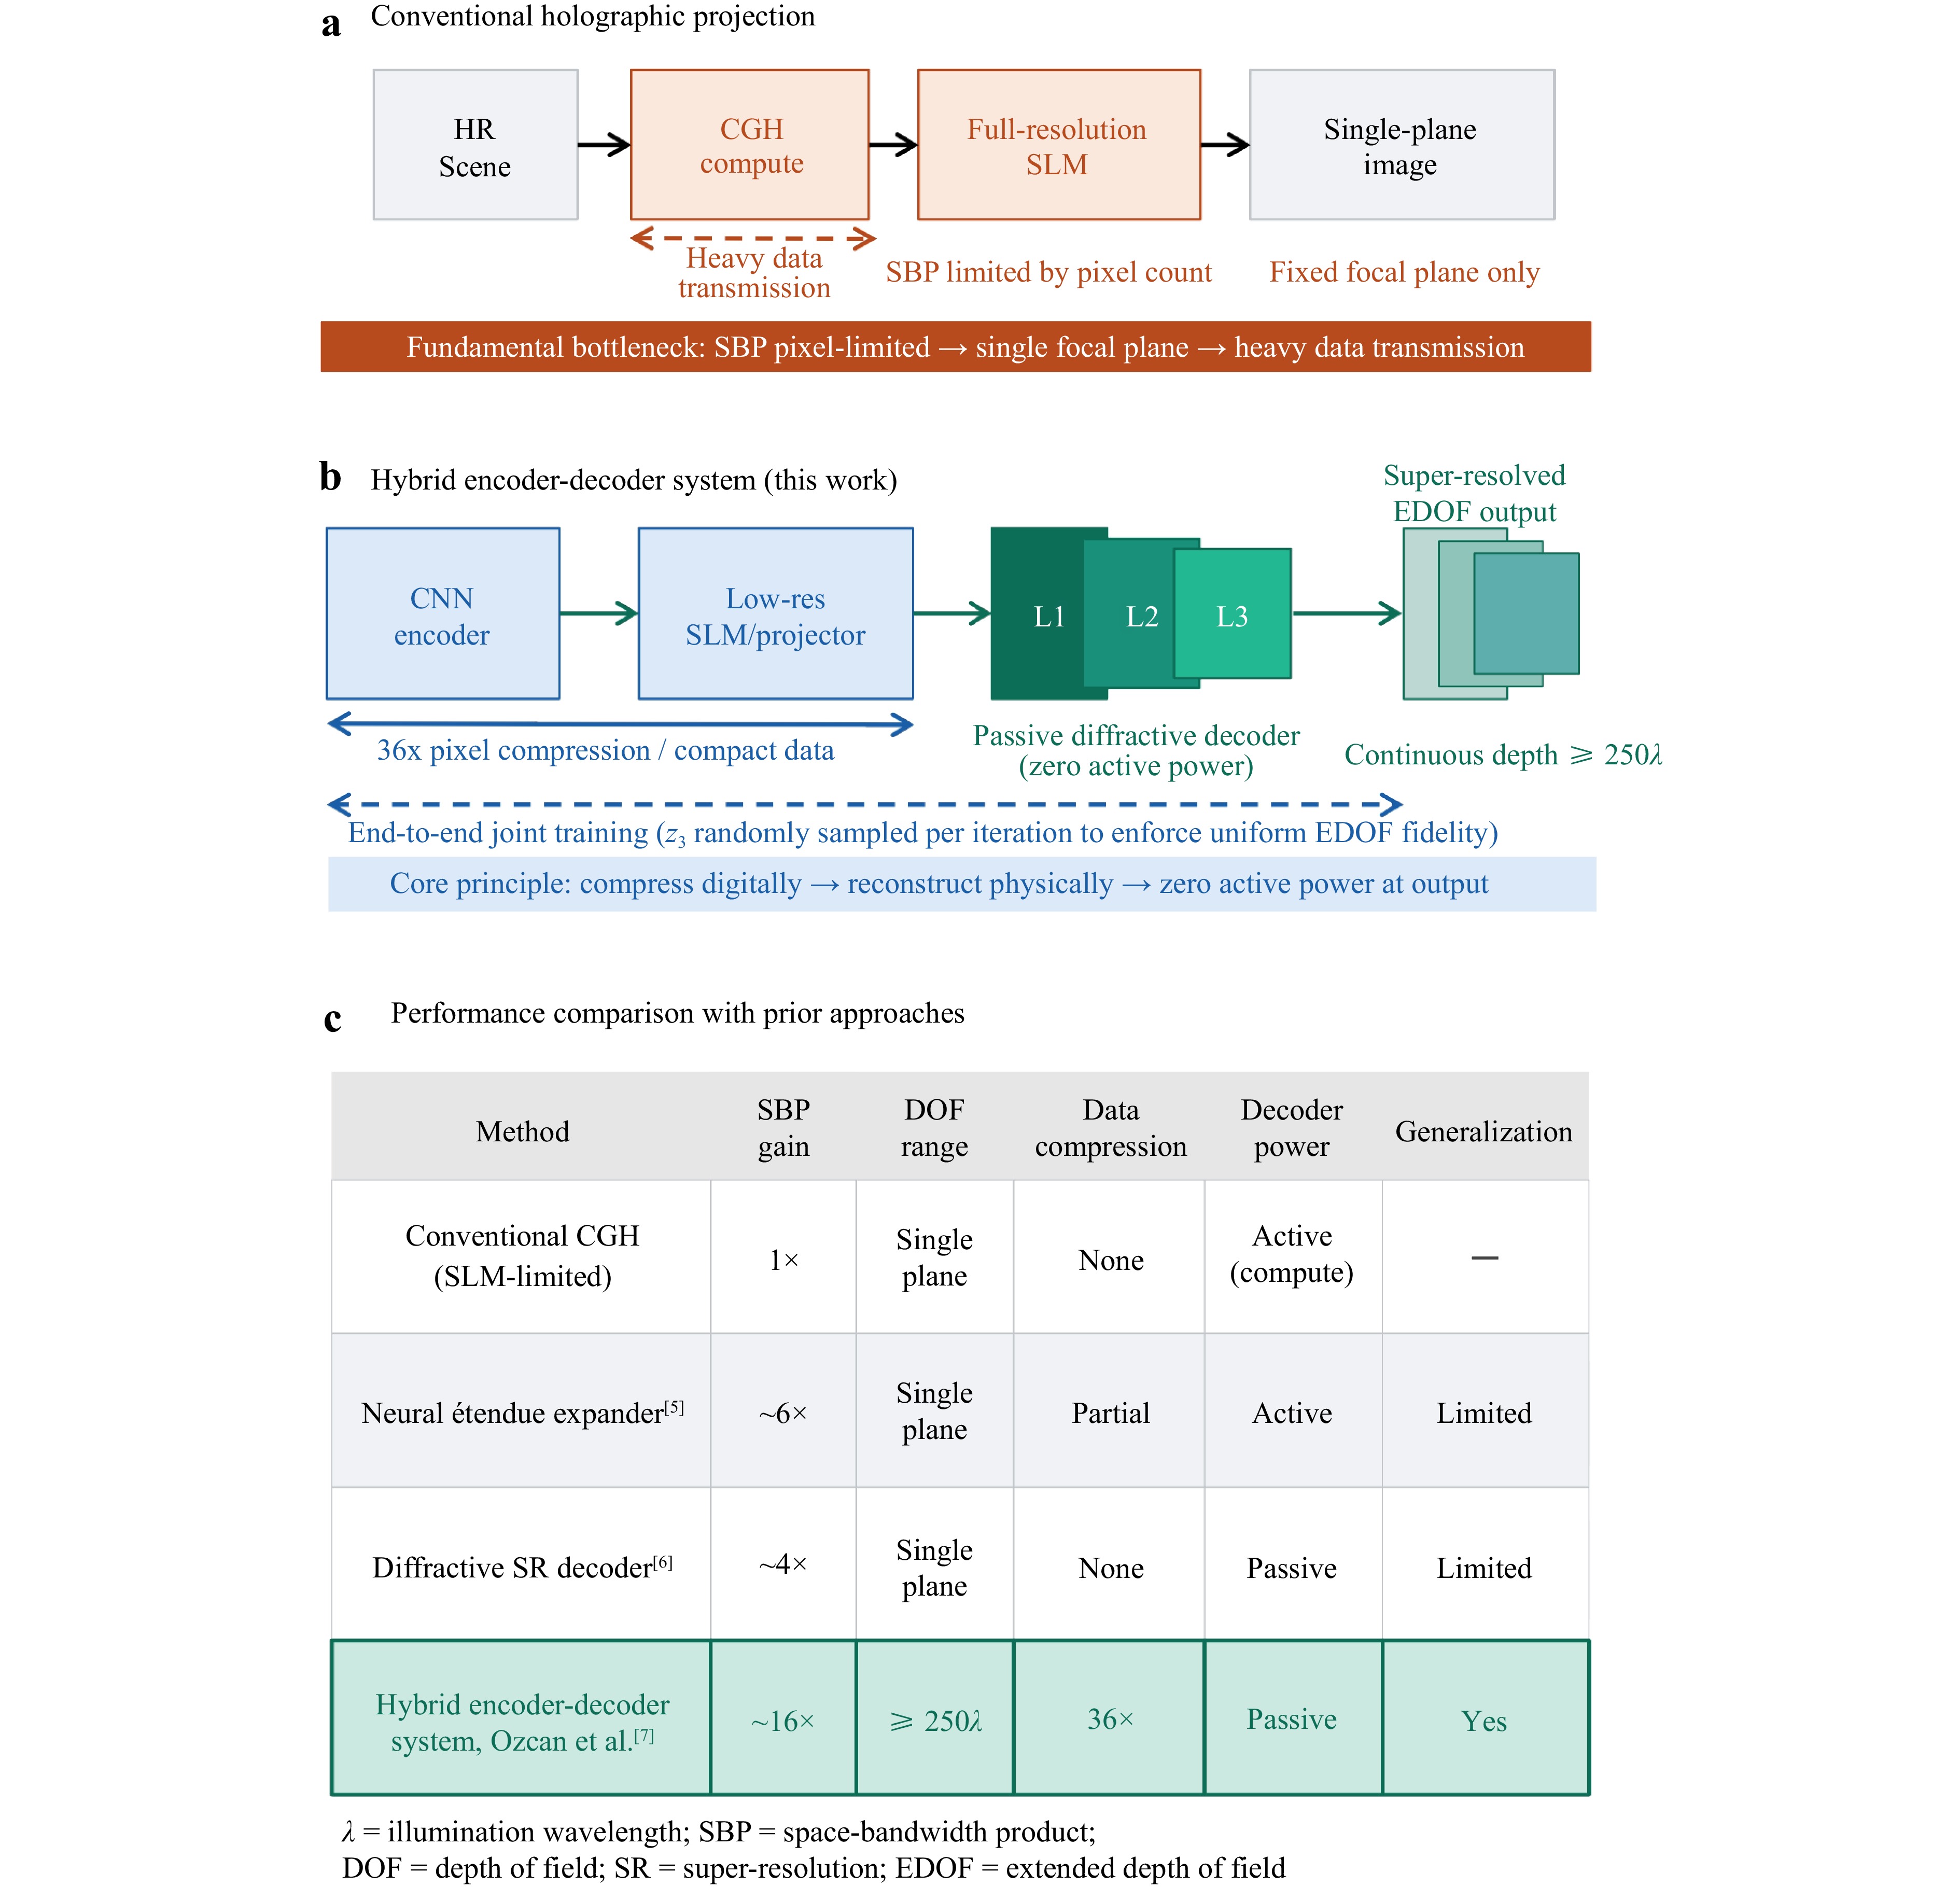
Ozcan et al.7 have demonstrated a hybrid system that resolved the projection problem (Fig. 1b). A lightweight convolutional neural network encoder compresses high-resolution input images 36-fold into compact phase patterns, which are then fed to a low-resolution SLM or projector. A jointly trained stack of passive diffractive layers (L1, L2, L3) reconstructs the wavefront downstream all-optically, thus synthesising super-resolved images across a continuous axial volume. The diffractive decoder—conceptually derived from the D2NN framework8 and the preceding single-plane SR decoder6—gains both digital front-end and volumetric depth coverage. Once fabricated, this hybrid system can operate as a permanently embedded analogue processor that does not require active power. The core training innovation is the randomised depth-sampling strategy, where the target reconstruction plane z3 is drawn uniformly from the full target DOF range at each iteration. This approach compels the system to maintain high fidelity across the entire axial volume instead of optimising a single focal plane through a learned generalisation—a common limitation in classical wavefront coding. The resulting system achieved an approximately 16-fold SBP improvement and a continuous extended DOF (EDOF) spanning ≥ 250λ in the simulation. Proof-of-concept experiments validated this approach at two wavelengths: a three-dimensionally printed single-layer decoder in the terahertz band (λ ≈ 750 nm) demonstrated a DOF of 50 mm (≈ 67λ), and an SLM-emulated layer at λ = 635 nm achieved 30 mm (≈ 47λ). External generalisations on 5,000 Quickdraw doodles spanning 100 unseen categories yielded a mean PSNR of 19.13±1.69 dB and an SSIM of 0.724±0.070, thereby confirming that the encoder-decoder combination learned a broadly applicable SR mapping instead of merely memorising the training distribution. Translating these numerical results into fabricated hardware requires robustness against two practical challenges: interlayer mechanical misalignment and finite-phase quantisation. The authors addressed both through an extended ‘vaccination’ training strategy originally introduced for misalignment-resilient diffractive networks9. By injecting controlled random displacements of the diffractive layers during training, the decoder acquired intrinsic tolerance to positional errors up to ±0.5λ laterally with less than 1 dB PSNR penalty. The same co-design philosophy applied to phase quantisation recovered the performance degradation to within 0.09 dB of the ideal even at 3-bit resolution, thereby encoding the fabrication constraints directly into the optimisation objective.
Whereas these results are compelling, the current implementation presents trade-offs that must be addressed in future studies. First, the experimental demonstrations used input images of only 24 × 24 pixels. Scaling to megapixel natural content would require substantially larger diffractive apertures and a corresponding expansion of training data. Second, the experimental DOF (47–67λ) is significantly smaller than the simulated DOF of ≥ 250λ. This limitation stemmed from using the single-layer architecture selected for fabrication simplicity and can be mitigated by transitioning to multilayer lithography. Third, visible-wavelength operations demand sub-micrometre feature sizes over centimetre-scale apertures. Although the wafer-scale fabrication of multilayer diffractive processors has been demonstrated10, the interlayer alignment, yield, and cost at display-relevant scales can be further improved. Finally, the system currently operates under monochromatic illumination; a polychromatic extension would require either an achromatic diffractive design or wavelength-multiplexed training, which may introduce additional complexity.
By accepting these trade-offs, Ozcan et al.7 have provided a new conceptual perspective to holographic projection: not as a monolithic computational task but as a deliberate partition between electronics and optics. State-of-the-art neural CGH networks can synthesise photorealistic 4K holograms in real time11,12; however, the output resolution remains restricted to the SLM pixel count. Integrating such a front end directly with a passive diffractive decoder would delegate resolution recovery and axial depth control entirely to the optics, thereby complementing previous large-étendue waveguide approaches13 that address field-of-view limitations in the eye box. Recent advances in all-optical tensor computing14 and diffractive generative modelling15 show a broader class of hybrid platforms in which digital intelligence is compiled into static optical hardware during deployment and require no runtime energy for inference. In addition to displays, the encoder-decoder principle may be applied to computational metrology and lensless microscopy16, where a passive extended-DOF projector can replace active axial scanning. This study highlights two critical areas for investigation: the scalability of end-to-end training when handling megapixel-scale content and the adaptability of the framework under broadband illumination.
HTML
-
This study was supported by the National Research and Development Program of China (2023YFB2804702), the National Natural Science Foundation of China (NSFC) (62550072, 62341508), the Shanghai Science and Technology Innovation Action Plan (25LN3201000, 25JD1405500, and 24JD1401500), and the Shanghai Municipal Science and Technology Major Project.

 DownLoad: